PhD Student @ Imperial · Research Intern @ NVIDIAPhD @ Imperial · Intern @ NVIDIA
Oliver Lu · 卢彦作
I work on real-time generation
01
About
I am a PhD student at Imperial College London, advised by Dr. Jiankang Deng, and currently a research intern at NVIDIA Research, working with Dr. Enze Xie and Prof. Song Han. My current research focuses on building Real-Time and Long-Video World Models, involving three main areas: (1) real-time generation, with a focus on achieving inference speeds where the processing time for each video chunk is less than its duration; (2) long-video generation, with the key challenge being the mitigation of error accumulation between chunks to maintain long-term consistency; and (3) interactive world models, with the objective of developing methods for effective control signal injection and responsive, timely feedback.
Before my PhD, I spent about two years at ByteDance Seed working on diffusion model acceleration, and received my bachelor's and master's degrees from Sun Yat-sen University.
My Chinese name is 卢彦作, and you can also call me Oliver Lu. I love watching anime and playing video games in my spare time. My favorite anime include Demon Slayer: Kimetsu no Yaiba (鬼滅の刃), Attack on Titan (進撃の巨人), Frieren: Beyond Journey's End (葬送のフリーレン), Eighty Six (86―エイティシックス―) and Violet Evergarden (ヴァイオレット・エヴァーガーデン). Recently, I've also been trying to get into landscape photography.
Feel free to explore my work below and reach out by email for any discussion.
02
News
- We released StreamRender-H3, which turns a world written in code into photorealistic video as you play. Built on MiniMax-H3 Ref2VA, it generates each 333–375 ms chunk in about 260 ms on 8×GB200, staying ahead of playback. The code is publicly available.
- RAVEN is accepted to NeurIPS 2026. See you in Sydney!
- I joined NVIDIA Research as a research intern in the Efficient AI Team, working with Dr. Enze Xie and Prof. Song Han on efficient generative models.
- We released RAVEN, a training-time test framework for distilling real-time autoregressive video generators, along with CM-GRPO, which brings online RL to consistency-model sampling. The code and models are publicly available.
- I started my PhD at Imperial College London under the supervision of Dr. Jiankang Deng, supported by a fully-funded doctoral scholarship. My research focuses on real-time and long-video world models.
- I left the ByteDance Seed Team after nearly two years. Sincere thanks to my close collaborators, including Weifeng Chen, Huafeng Kuang, Yuxi Ren, Xin Xia, Jie Wu and Xing Wang, and to my manager Xuefeng Xiao for this valuable opportunity.
- We brought the acceleration recipes of the Seedream models to Bagel, a unified model for understanding and generation, and further refined the Hyper-SD methodology into Hyper-Bagel.
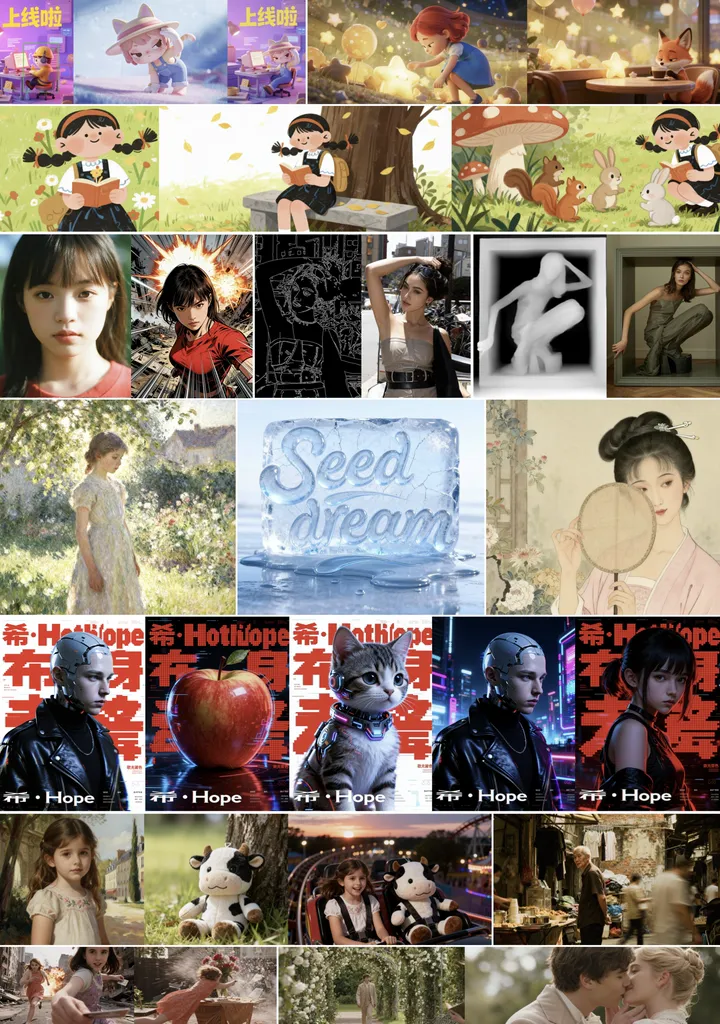
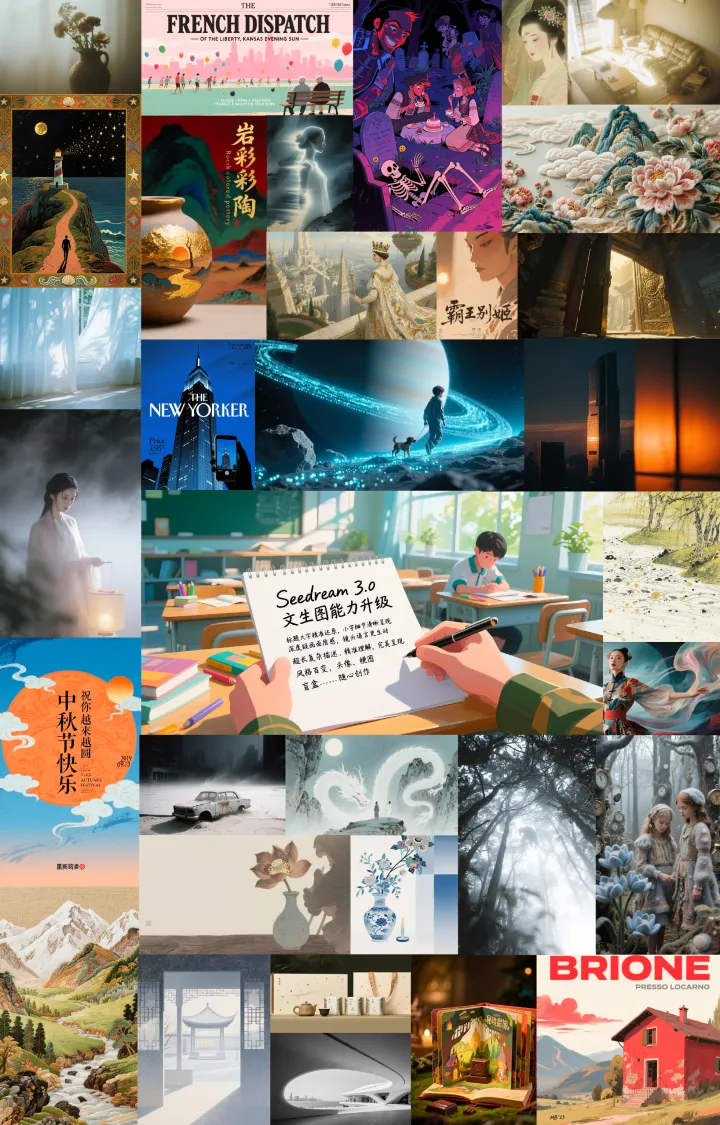
- As a core contributor, I worked on the acceleration of Seedream 4.0, which is fully deployed on ByteDance platforms including Doubao. Its technical report has also been released.
- DMDX, our attempt to combine score distillation with adversarial training objectives, is accepted to ICCV 2025 as a Highlight.
- I graduated from Sun Yat-sen University with an MEng degree and joined the ByteDance Seed Team full-time.
- I contributed to the acceleration of Seedream 3.0, which is fully deployed on ByteDance platforms including Doubao. Its technical report has also been released.
- Hyper-SD is accepted to NeurIPS 2024.
- I took charge of training the FLUX and SD3 acceleration LoRAs that extend Hyper-SD, which once again made the Hugging Face Trending list.
- ByteEdit, our work on accelerating diffusion-based image editing, is accepted to ECCV 2024. As co-first author, I worked on its adversarial training and reinforcement learning.
- We released Hyper-SD, a new state-of-the-art acceleration technique for diffusion models, with models distilled from SD1.5 and SDXL. It was featured on the Hugging Face Trending list.
- My first work on diffusion models, CFLD for pose transfer, is accepted to CVPR 2024 as a Highlight. Both the model and code are publicly available.
- I joined ByteDance as a research intern, working on diffusion model acceleration.
03
Publications
* Equal contribution.
04
Projects
05
Experience
Sep 2026 – Present
Research on efficient generative models, from acceleration algorithms to training and inference infrastructure. Developed StreamRender‑H3, which renders interactive worlds written in code into photorealistic video in real time.
ByteDance Seed
Research Scientist (Jun – Sep 2025) · Research Intern (Dec 2023 – Jun 2025)
Hosts: Yuxi Ren, Jie Wu and Xuefeng Xiao
Dec 2023 – Sep 2025
Research on few-step image and video generation through progressive, consistency, score and adversarial distillation, together with RLHF. Worked on accelerating the Seedream 3.0 and 4.0 image generation models used across ByteDance products.
06
Education
Oct 2025 – Present
Sun Yat-sen University
MEng (2025) and BEng (2022) in Computer Science
Sep 2018 – Jun 2025
07
Honors and Service
Honors
2025 – 2029Fully-Funded Doctoral Scholarship Imperial College London
2024China National Scholarship
Reviewer
Conferences
- CVPR
- NeurIPS
- ECCV
- AAAI
- ACM MM
Journals
- IEEE TPAMI
- IEEE TIP
- IEEE TVCG
- IEEE TCSVT
- IEEE TMM
- ACM CSUR